

Improve model card: Associate with WebWeaver paper and add Quick Start
Browse filesThis PR updates the model card for the `Tongyi-DeepResearch-30B-A3B` model to accurately reflect its association with the [WebWeaver: Structuring Web-Scale Evidence with Dynamic Outlines for Open-Ended Deep Research](https://huggingface.co/papers/2509.13312) paper.
Specifically, it:
- Links directly to the associated WebWeaver paper.
- Adds explicit links to the project blog and GitHub repository for easy access.
- Incorporates a detailed "Quick Start" section with environment setup, installation, and inference instructions, directly sourced from the GitHub repository.
- Updates the "Model Download" section with a clear table of download links.
- Includes relevant benchmark results and a list of related papers from the Deep Research Agent Family.
- Adds comprehensive "News", "Misc", "Talent Recruitment", and "Contact Information" sections from the GitHub README.
- Adds a BibTeX citation for the WebWeaver paper alongside the existing model citation.
These changes enhance the model card's completeness, usability, and discoverability.
|
@@ -1,14 +1,26 @@
|
|
| 1 |
---
|
| 2 |
-
license: apache-2.0
|
| 3 |
language:
|
| 4 |
- en
|
| 5 |
-
pipeline_tag: text-generation
|
| 6 |
library_name: transformers
|
|
|
|
|
|
|
| 7 |
---
|
| 8 |
|
| 9 |
-
#
|
|
|
|
|
|
|
|
|
|
|
|
|
| 10 |
|
| 11 |
-
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 12 |
|
| 13 |
More details can be found in our 📰 [Tech Blog](https://tongyi-agent.github.io/blog/introducing-tongyi-deep-research).
|
| 14 |
|
|
@@ -21,12 +33,128 @@ More details can be found in our 📰 [Tech Blog](https://tongyi-agent.github.io
|
|
| 21 |
- 🔁 **End-to-end reinforcement learning**: We employ a strictly on-policy RL approach based on a customized Group Relative Policy Optimization framework, with token-level policy gradients, leave-one-out advantage estimation, and selective filtering of negative samples to stabilize training in a non‑stationary environment.
|
| 22 |
- 🤖 **Agent Inference Paradigm Compatibility**: At inference, Tongyi-DeepResearch is compatible with two inference paradigms: ReAct, for rigorously evaluating the model's core intrinsic abilities, and an IterResearch-based 'Heavy' mode, which uses a test-time scaling strategy to unlock the model's maximum performance ceiling.
|
| 23 |
|
| 24 |
-
#
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 25 |
|
| 26 |
-
You can download the model then run the inference scipts in https://github.com/Alibaba-NLP/DeepResearch.
|
| 27 |
|
|
|
|
| 28 |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 29 |
```bibtex
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
| 30 |
@misc{tongyidr,
|
| 31 |
author={Tongyi DeepResearch Team},
|
| 32 |
title={Tongyi-DeepResearch},
|
|
|
|
| 1 |
---
|
|
|
|
| 2 |
language:
|
| 3 |
- en
|
|
|
|
| 4 |
library_name: transformers
|
| 5 |
+
license: apache-2.0
|
| 6 |
+
pipeline_tag: text-generation
|
| 7 |
---
|
| 8 |
|
| 9 |
+
# Tongyi DeepResearch: WebWeaver
|
| 10 |
+
|
| 11 |
+
This repository contains **Tongyi DeepResearch**, an agentic large language model, which is associated with the paper [WebWeaver: Structuring Web-Scale Evidence with Dynamic Outlines for Open-Ended Deep Research](https://huggingface.co/papers/2509.13312).
|
| 12 |
+
|
| 13 |
+
<div align="center" style="line-height: 1;">
|
| 14 |
|
| 15 |
+
[](https://huggingface.co/papers/2509.13312) |
|
| 16 |
+
[](https://github.com/Alibaba-NLP/DeepResearch) |
|
| 17 |
+
[](https://tongyi-agent.github.io/blog/introducing-tongyi-deep-research/)
|
| 18 |
+
|
| 19 |
+
</div>
|
| 20 |
+
|
| 21 |
+
## Introduction
|
| 22 |
+
|
| 23 |
+
We present **Tongyi DeepResearch**, an agentic large language model featuring 30 billion total parameters, with only 3 billion activated per token. Developed by Tongyi Lab, the model is specifically designed for **long-horizon, deep information-seeking** tasks. Tongyi-DeepResearch demonstrates state-of-the-art performance across a range of agentic search benchmarks, including Humanity's Last Exam, BrowserComp, BrowserComp-ZH, WebWalkerQA, GAIA, xbench-DeepSearch and FRAMES.
|
| 24 |
|
| 25 |
More details can be found in our 📰 [Tech Blog](https://tongyi-agent.github.io/blog/introducing-tongyi-deep-research).
|
| 26 |
|
|
|
|
| 33 |
- 🔁 **End-to-end reinforcement learning**: We employ a strictly on-policy RL approach based on a customized Group Relative Policy Optimization framework, with token-level policy gradients, leave-one-out advantage estimation, and selective filtering of negative samples to stabilize training in a non‑stationary environment.
|
| 34 |
- 🤖 **Agent Inference Paradigm Compatibility**: At inference, Tongyi-DeepResearch is compatible with two inference paradigms: ReAct, for rigorously evaluating the model's core intrinsic abilities, and an IterResearch-based 'Heavy' mode, which uses a test-time scaling strategy to unlock the model's maximum performance ceiling.
|
| 35 |
|
| 36 |
+
# Model Download
|
| 37 |
+
|
| 38 |
+
You can directly download the model by following the links below.
|
| 39 |
+
|
| 40 |
+
| Model | Download Links | Model Size | Context Length |
|
| 41 |
+
| :-----------------: | :-----------------------------------------: | :----------: | :--------------: |
|
| 42 |
+
| Tongyi-DeepResearch-30B-A3B | [🤗 HuggingFace](https://huggingface.co/Alibaba-NLP/Tongyi-DeepResearch-30B-A3B)<br> [🤖 ModelScope](https://modelscope.cn/models/iic/Tongyi-DeepResearch-30B-A3B) | 30B-A3B | 128K |
|
| 43 |
+
|
| 44 |
+
# News
|
| 45 |
+
|
| 46 |
+
[2025/09/17]🔥 We have released **Tongyi-DeepResearch-30B-A3B**.
|
| 47 |
+
|
| 48 |
+
# Deep Research Benchmark Results
|
| 49 |
+
<p align="center">
|
| 50 |
+
<img width="100%" src="https://github.com/Alibaba-NLP/DeepResearch/raw/main/assets/benchmark.png">
|
| 51 |
+
</p>
|
| 52 |
+
|
| 53 |
+
## Quick Start
|
| 54 |
+
|
| 55 |
+
This guide provides instructions for setting up the environment and running inference scripts located in the [inference](https://github.com/Alibaba-NLP/DeepResearch/tree/main/inference/) folder.
|
| 56 |
+
|
| 57 |
+
### 1. Environment Setup
|
| 58 |
+
- Recommended Python version: **3.10.0** (using other versions may cause dependency issues).
|
| 59 |
+
- It is strongly advised to create an isolated environment using `conda` or `virtualenv`.
|
| 60 |
+
|
| 61 |
+
```bash
|
| 62 |
+
# Example with Conda
|
| 63 |
+
conda create -n react_infer_env python=3.10.0
|
| 64 |
+
conda activate react_infer_env
|
| 65 |
+
```
|
| 66 |
+
|
| 67 |
+
### 2. Installation
|
| 68 |
+
|
| 69 |
+
Install the required dependencies:
|
| 70 |
+
```bash
|
| 71 |
+
pip install -r requirements.txt
|
| 72 |
+
```
|
| 73 |
+
|
| 74 |
+
### 3. Prepare Evaluation Data
|
| 75 |
+
- Create a folder named `eval_data/` in the project root.
|
| 76 |
+
- Place your QA file in **JSONL** format inside this directory, e.g. `eval_data/example.jsonl`.
|
| 77 |
+
- Each line must be a JSON object that includes **both** of the following keys:
|
| 78 |
+
```json
|
| 79 |
+
{"question": "...","answer": "..."}
|
| 80 |
+
```
|
| 81 |
+
- A sample file is provided in the `eval_data` folder for reference.
|
| 82 |
+
- If you plan to use the *file parser* tool, **prepend the file name to the `question` field** and place the referenced file inside the `eval_data/file_corpus/` directory.
|
| 83 |
+
|
| 84 |
+
### 4. Configure the Inference Script
|
| 85 |
+
- Open `run_react_infer.sh` and modify the following variables as instructed in the comments:
|
| 86 |
+
* `MODEL_PATH` - path to the local or remote model weights.
|
| 87 |
+
* `DATASET` - path to the evaluation set, e.g. `example`.
|
| 88 |
+
* `OUTPUT_PATH` - path for saving the prediction results, e.g. `./outputs`.
|
| 89 |
+
- Depending on the tools you enable (retrieval, calculator, web search, etc.), provide the required `API_KEY`, `BASE_URL`, or other credentials. Each key is explained inline in the bash script.
|
| 90 |
|
|
|
|
| 91 |
|
| 92 |
+
### 5. Run the Inference Script
|
| 93 |
|
| 94 |
+
```bash
|
| 95 |
+
bash run_react_infer.sh
|
| 96 |
+
```
|
| 97 |
+
---
|
| 98 |
+
|
| 99 |
+
With these steps, you can fully prepare the environment, configure the dataset, and run the model. For more details, consult the inline comments in each script or open an issue.
|
| 100 |
+
|
| 101 |
+
## Benchmark Evaluation
|
| 102 |
+
|
| 103 |
+
We provide benchmark evaluation scripts for various datasets. Please refer to the [evaluation scripts](https://github.com/Alibaba-NLP/DeepResearch/tree/main/evaluation/) directory for more details.
|
| 104 |
+
|
| 105 |
+
## Deep Research Agent Family
|
| 106 |
+
|
| 107 |
+
<p align="center">
|
| 108 |
+
<img width="100%" src="https://github.com/Alibaba-NLP/DeepResearch/raw/main/assets/family.png">
|
| 109 |
+
</p>
|
| 110 |
+
|
| 111 |
+
Tongyi DeepResearch also has an extensive deep research agent family. You can find more information in the following paper:
|
| 112 |
+
|
| 113 |
+
[1] [WebWalker: Benchmarking LLMs in Web Traversal](https://arxiv.org/pdf/2501.07572)<br>
|
| 114 |
+
[2] [WebDancer: Towards Autonomous Information Seeking Agency](https://arxiv.org/pdf/2505.22648)<br>
|
| 115 |
+
[3] [WebSailor: Navigating Super-human Reasoning for Web Agent](https://arxiv.org/pdf/2507.02592)<br>
|
| 116 |
+
[4] [WebShaper: Agentically Data Synthesizing via Information-Seeking Formalization](https://arxiv.org/pdf/2507.15061)<br>
|
| 117 |
+
[5] [WebWatcher: Breaking New Frontier of Vision-Language Deep Research Agent](https://arxiv.org/pdf/2508.05748)<br>
|
| 118 |
+
[6] [WebResearcher: Unleashing unbounded reasoning capability in Long-Horizon Agents](https://arxiv.org/pdf/2509.13309)<br>
|
| 119 |
+
[7] [ReSum: Unlocking Long-Horizon Search Intelligence via Context Summarization](https://arxiv.org/pdf/2509.13313)<br>
|
| 120 |
+
[8] [WebWeaver: Structuring Web-Scale Evidence with Dynamic Outlines for Open-Ended Deep Research](https://arxiv.org/pdf/2509.13312)<br>
|
| 121 |
+
[9] [WebSailor-V2: Bridging the Chasm to Proprietary Agents via Synthetic Data and Scalable Reinforcement Learning](https://arxiv.org/pdf/2509.13305)<br>
|
| 122 |
+
[10] [Scaling Agents via Continual Pre-training](https://arxiv.org/pdf/2509.13310)<br>
|
| 123 |
+
[11] [Towards General Agentic Intelligence via Environment Scaling](https://arxiv.org/pdf/2509.13311)
|
| 124 |
+
|
| 125 |
+
|
| 126 |
+
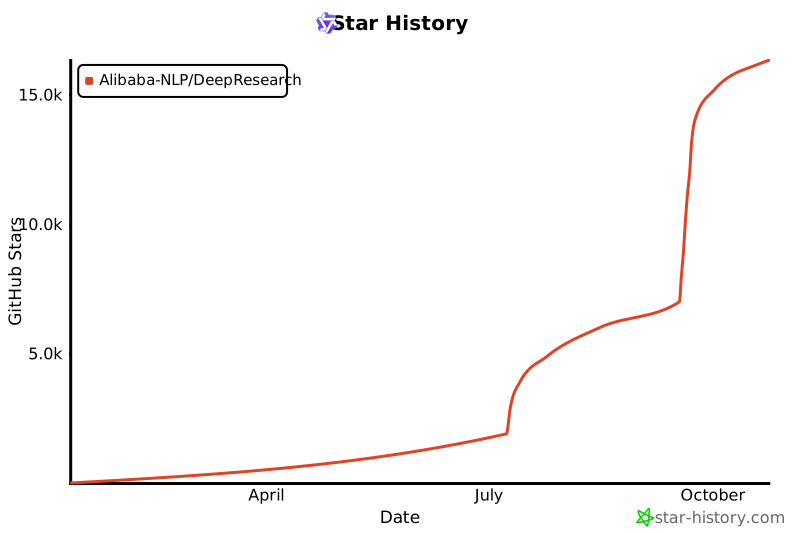
## 🌟 Misc
|
| 127 |
+
|
| 128 |
+
<div align="center">
|
| 129 |
+
|
| 130 |
+
[](https://www.star-history.com/#Alibaba-NLP/DeepResearch&Date)
|
| 131 |
+
|
| 132 |
+
</div>
|
| 133 |
+
|
| 134 |
+
## 🚩 Talent Recruitment
|
| 135 |
+
|
| 136 |
+
🔥🔥🔥 We are hiring! Research intern positions are open (based in Hangzhou、Beijing、Shanghai)
|
| 137 |
+
|
| 138 |
+
📚 **Research Area**:Web Agent, Search Agent, Agent RL, MultiAgent RL, Agentic RAG
|
| 139 |
+
|
| 140 |
+
☎️ **Contact**:[yongjiang.jy@alibaba-inc.com]()
|
| 141 |
+
|
| 142 |
+
## Contact Information
|
| 143 |
+
|
| 144 |
+
For communications, please contact Yong Jiang (yongjiang.jy@alibaba-inc.com).
|
| 145 |
+
|
| 146 |
+
## Citation
|
| 147 |
```bibtex
|
| 148 |
+
@misc{webweaver2025,
|
| 149 |
+
title={WebWeaver: Structuring Web-Scale Evidence with Dynamic Outlines for Open-Ended Deep Research},
|
| 150 |
+
author={Tongyi DeepResearch Team},
|
| 151 |
+
year={2025},
|
| 152 |
+
eprint={2509.13312},
|
| 153 |
+
archivePrefix={arXiv},
|
| 154 |
+
primaryClass={cs.CL},
|
| 155 |
+
url={https://huggingface.co/papers/2509.13312}
|
| 156 |
+
}
|
| 157 |
+
|
| 158 |
@misc{tongyidr,
|
| 159 |
author={Tongyi DeepResearch Team},
|
| 160 |
title={Tongyi-DeepResearch},
|